How Large Language Models Like ChatGPT Generate Text
When you type a question into ChatGPT and receive several paragraphs of coherent text seconds later, the process can feel surprisingly similar to talking with another person. The response follows your instructions, refers to earlier parts of the conversation, adjusts its tone, explains concepts, and sometimes connects ideas that were never explicitly mentioned in your question. That can make it seem as though a large language model first thinks of a complete answer somewhere inside the computer and then simply types it onto the screen.
That is not how the process works. Large language models generate text incrementally, using patterns learned during training to predict what should come next based on the information already available. The model does not normally compose an entire finished paragraph and then reveal it word by word. Instead, it repeatedly predicts another small piece of text, adds that piece to the existing context, and then uses the expanded context to make the next prediction.
The basic mechanism sounds surprisingly simple. The remarkable part is the scale. When next-token prediction is performed by an enormous neural network trained across vast amounts of language and then refined to follow instructions, the system can produce writing that looks far more sophisticated than the phrase “predicting the next token” initially suggests.
Everything Begins With Your Prompt
The generation process begins with whatever information the model receives. This can include your current question, earlier messages in the conversation, instructions describing how the system should behave, and sometimes information supplied by tools or other sources.
This collection of information forms the model’s context. Context matters enormously because the same sentence can require completely different responses depending on what appeared before it. If you simply write “Make it shorter,” the model needs the previous conversation to understand what “it” refers to. If you ask, “What happened next?” the meaning depends entirely on what was being discussed.
A language model therefore does not process each message as an isolated command. It interprets the new request within the information currently available to it.
The Model Does Not Read Text Exactly as You Do
Before your prompt can be processed, the text is divided into smaller units called tokens. A token can represent an entire word, part of a word, punctuation, or another frequently occurring piece of text.
A common word may fit into a single token, while a longer or unusual word might be divided into several tokens. Different languages and writing systems can also be tokenized differently.
This matters because tokens are the basic units the language model works with. When people casually say that a model “predicts the next word,” that is a useful simplification, but technically it is usually predicting the next token.
Your sentence therefore becomes a sequence of tokens before the neural network begins processing it.
Tokens Are Converted Into Numbers
Computers do not understand words directly. They perform mathematical operations on numbers.
Each token is therefore converted into a numerical representation that the neural network can process. These representations are often called embeddings.
An embedding does much more than simply assign a token an identification number. Through training, the model develops representations that capture useful relationships between language and concepts.
Words and ideas appearing in similar contexts can develop related representations. Concepts involving cities, countries, animals, emotions, programming, history, or thousands of other domains can form complex relationships within the model’s internal space.
This allows the system to process meaning through mathematical patterns rather than through dictionary definitions stored beside individual words.
Position Matters Too
Language depends heavily on order. “Dog bites man” and “man bites dog” contain the same three words but describe very different situations.
The model therefore needs information about where tokens appear within the sequence.
Modern language models use mechanisms that allow them to represent or infer positional relationships between tokens. This helps the system distinguish between words appearing earlier and later and understand how different parts of a sentence or conversation relate.
Without information about order, language would become little more than a bag of disconnected words.
Transformers Made Long-Range Relationships Easier to Handle
Most modern large language models are based on an architecture called the transformer. Transformers became extremely important because they are particularly effective at processing relationships between different parts of a sequence.
Earlier language-processing systems often struggled with information separated by long distances in text. Transformers introduced mechanisms that made it much easier for models to determine which parts of the available context are relevant to one another.
One of the most important mechanisms is called attention.
Attention allows the model to weigh relationships between tokens while processing the context. Rather than treating every earlier piece of text as equally important, the system can identify patterns indicating that certain information is especially relevant to the current calculation.
Attention Helps the Model Follow Context
Consider the sentence, “Maria put the cake in the refrigerator because it needed to stay cold.” Understanding the word “it” requires connecting it to the cake rather than Maria or the refrigerator.
Humans resolve this relationship almost effortlessly because we understand language and the situation being described.
A language model uses learned patterns and attention mechanisms to identify relationships across the text.
In a longer conversation, the same principle becomes much more powerful. If you told the model several paragraphs earlier that you wanted an explanation written for beginners, that instruction can influence how later responses are generated.
Attention does not mean the model is consciously focusing in the human sense. It is a mathematical mechanism that helps determine which relationships within the context should influence processing.
The Prompt Passes Through Many Neural Network Layers
Once the tokens have been represented numerically, the information passes through many layers of the neural network.
Each layer transforms the representations based on patterns learned during training. Early processing may capture some relationships, while later layers combine information into increasingly sophisticated representations.
By the time the input has passed through the network, the model has produced a rich internal representation of the context.
This representation is not a sentence written secretly inside the machine. It consists of large collections of numerical values encoding relationships relevant to predicting what should come next.
The model is now ready to generate.
The Model Calculates Possible Next Tokens
Suppose you ask, “What is the capital of France?”
After processing the prompt, the model calculates probabilities across possible next tokens.
Some continuations will receive extremely low probabilities because they make little sense in context. Others will receive much higher probabilities.
A likely response might begin with “The” or “Paris,” depending on how the answer is structured.
The model selects one token according to the generation strategy being used.
That token becomes part of the response.
Then something crucial happens: the newly generated token becomes part of the context for the next prediction.
Text Is Generated One Step at a Time
Suppose the model begins with “Paris.”
The next prediction is now based on your original prompt plus the generated word “Paris.” The model might predict “is” next.
Now the context contains “Paris is.”
The next prediction might be “the.”
Then “capital.”
Then “of.”
Then “France.”
This simplified example demonstrates the fundamental process. The model repeatedly predicts another token based on everything available so far.
Long responses are produced through thousands of these small prediction steps.
What looks like a complete argument emerging from the system is created incrementally.
Predicting the Next Token Is Harder Than It Sounds
The phrase “next-token prediction” can make language models sound like sophisticated autocomplete systems.
In one sense, that comparison is correct. Both attempt to predict what should come next.
The difference is the complexity required to perform that prediction well.
Consider the beginning of a sentence such as, “The scientist rejected the original explanation because…”
To continue convincingly, a model may need to understand grammar, scientific reasoning, the previous discussion, the meaning of “original explanation,” and what kind of evidence might logically cause someone to reject it.
Now imagine predicting the next token across programming, law, history, poetry, mathematics, casual conversation, scientific writing, and thousands of other domains.
To become exceptionally good at prediction, a model needs to learn an enormous amount about the structures and concepts represented in language.
Next-token prediction is simple as an objective but extraordinarily complicated in practice.
The Model Learned Those Patterns During Training
Before a language model can generate useful text, it goes through extensive training.
During training, the model processes enormous amounts of language and repeatedly attempts to predict missing or upcoming tokens.
At first, its predictions are poor.
The training system measures the errors and adjusts the model’s internal parameters slightly.
Those parameters are the enormous collection of numerical values that determine how information moves through the neural network.
This cycle happens repeatedly across vast quantities of examples.
Gradually, the model becomes better at predicting language.
Parameters Store Learned Patterns in a Distributed Way
Large language models can contain enormous numbers of parameters.
It is tempting to imagine these parameters as individual storage boxes containing facts, with one parameter holding information about Paris and another storing the rules of English grammar.
That is not how the information is organized.
Knowledge is distributed across the network.
Many parameters can contribute to representing a concept, while the same parameters may participate in many different behaviors.
This distributed representation is one reason inspecting a model and locating the exact physical place where one specific fact is “stored” is difficult.
The model behaves more like a vast interconnected pattern system than a conventional database.
A Language Model Is Not Usually Searching for a Stored Paragraph
When ChatGPT produces an explanation, it is generally not searching through its training material for an existing paragraph that perfectly answers the question and then pasting it.
Instead, it generates a new sequence using patterns encoded during training.
This distinction explains why the same request can produce differently worded answers and why a model can respond to combinations of ideas that may never have appeared together in exactly the same form.
Training shapes the model’s ability to generate language. Generation uses that learned structure to construct the current response.
Retrieval systems can also be connected to language models, but retrieval and language generation are separate processes.
Why Responses Are Not Always Identical
At many points during generation, several next tokens may be reasonable.
Suppose you ask the model to begin a story about a mysterious house. A sentence might plausibly begin with “At,” “The,” “Nobody,” “When,” or many other words.
The model assigns probabilities to possible continuations.
Generation settings can determine how conservatively or creatively the system selects among them. If the system always chose the highest-probability token, responses could become repetitive or overly predictable.
Allowing controlled variation produces more diverse language.
This is why asking the same creative question several times can generate different responses even though the underlying model is the same.
Temperature Influences Variation
One concept commonly associated with text generation is temperature.
Temperature affects how strongly the system favors the most probable options over less probable but still plausible alternatives.
Lower-temperature generation generally produces more predictable outputs because the model strongly favors high-probability tokens.
Higher-temperature generation allows more variation and can produce more surprising results, although excessive randomness can reduce coherence.
The ideal setting depends on the task.
A creative story can benefit from some unpredictability. A factual technical explanation generally benefits from greater consistency.
Temperature does not make the model more or less intelligent. It changes how its existing predictions are sampled.
The Model Builds Sentences Without Planning Every Word in Advance
Because generation occurs token by token, the model does not necessarily know the exact final wording of a paragraph before beginning it.
This is one reason language generation is so interesting.
The response develops as new tokens become part of the context.
The model can still produce structured writing because training has exposed it to enormous numbers of examples of essays, explanations, arguments, stories, conversations, lists, and other formats.
It has learned patterns associated with how these structures usually unfold.
In more sophisticated systems, additional reasoning or planning processes may also help organize difficult responses before or during generation. Even then, the visible text ultimately needs to be generated as a sequence of tokens.
How Does the Model Know When to Stop?
Stopping is also part of prediction.
During training, the model learns patterns associated with completed responses, documents, conversations, and other boundaries.
When generating text, it can produce a special signal indicating that the response should end.
System limits can also stop generation if the output becomes too long.
This means the model is not simply predicting words forever.
The end of a response is itself part of the learned structure of language generation.
Context Windows Create a Working Space
Language models can only process a certain amount of information at one time. This capacity is commonly called the context window.
The context can include instructions, conversation history, documents, tool results, and the text being generated.
Larger context windows allow models to work with more information simultaneously.
This can be extremely useful for analyzing long documents or maintaining complicated conversations.
However, a context window should not be confused with permanent memory.
Information can influence the response while it is present in context without becoming permanently encoded into the model’s trained parameters.
Training and Conversation Are Different Things
Suppose you tell a language model, “My fictional character is named Daniel and owns a bakery.”
The model can use that information later in the conversation because it exists in the available context.
That does not mean the underlying neural network has immediately been retrained to permanently contain this information.
Training changes the model’s parameters and is a much more intensive process.
Context provides temporary information the already-trained model can use.
Some AI systems can also have separate memory mechanisms, but those should still be distinguished from the model’s original training.
Instruction Following Requires Additional Training
A model trained only to predict text may be capable of generating impressive language but still be awkward to use as an assistant.
If you ask it a question, it might continue the question rather than answer it.
Developers therefore perform additional training designed to improve instruction following.
The model can be shown examples of useful conversations, evaluated on its responses, and trained using various forms of human or automated feedback.
This helps shape behavior such as answering directly, following formatting requests, acknowledging uncertainty, avoiding certain harmful outputs, and adapting to different tasks.
The result is a system that behaves much more like an assistant than a raw text predictor.
Why Large Language Models Can Follow Style Instructions
If you ask a model to explain something simply, write formally, use full paragraphs, or imitate the structure of a news report, it can often adjust its output.
This ability comes from patterns learned during training.
The model has encountered many different writing styles and understands statistical relationships between instructions and the language structures associated with them.
Your prompt changes the context, which changes the probability distribution over future tokens.
A request for a formal explanation makes formal vocabulary and sentence structures more likely. A request for a children’s explanation changes those probabilities in another direction.
Style control is therefore another consequence of conditional prediction.
How Can a Text Predictor Write Computer Code?
Computer code is also structured language.
Programming languages contain syntax, patterns, conventions, functions, relationships, and common problem-solving structures.
Models trained on suitable programming-related information can learn those patterns.
When asked to write code, the model predicts tokens that form plausible programming structures rather than ordinary prose.
This can produce surprisingly sophisticated software.
However, just as fluent natural language can contain factual errors, plausible-looking code can contain bugs.
The model’s ability to generate something that looks correct does not guarantee that the program behaves correctly.
Testing remains essential.
Why Models Can Translate Languages
Translation also emerges naturally from learning relationships across languages.
If a model has encountered sufficient multilingual information, it can develop representations connecting concepts expressed in different linguistic forms.
The English word “house,” the German “Haus,” the Spanish “casa,” and equivalent words in other languages can become connected through shared contexts and meanings.
When translating, the model does not need to replace every word individually.
It can use the broader context to generate a sentence expressing approximately the same meaning in another language.
This allows modern language models to handle expressions where literal word-for-word translation would sound unnatural.
Why Models Can Summarize
Summarization requires identifying which information in a passage matters most and generating a shorter representation of it.
Language models learn patterns from examples of descriptions, explanations, headlines, abstracts, summaries, and other compressed forms of information.
When given a long passage and asked to summarize it, the model processes the text as context and generates a shorter sequence that is statistically consistent with the important concepts it identified.
This can work remarkably well, but information can still be omitted or misrepresented.
For important documents, a generated summary should not automatically be treated as a perfect substitute for the original.
Why Hallucinations Happen
One of the most important limitations of large language models comes directly from how they generate text.
The model is optimized to produce plausible continuations.
Plausibility and truth are not the same thing.
If the model has weak information about a topic, it may still generate an answer because producing language is exactly what it was trained to do.
The result can be a fabricated date, source, quotation, person, event, or technical detail that sounds entirely believable.
This phenomenon is commonly called hallucination.
The model is not necessarily deliberately lying. It is generating a plausible sequence that happens to be factually incorrect.
Tools Can Make Language Models More Reliable
Modern AI systems increasingly combine language models with external tools.
If current information is required, the model can search the web or query a database. If a precise calculation is needed, it can use a calculator or execute code. If a user asks about a document, the system can retrieve the relevant section.
This creates an important distinction between what the model remembers from training and what the broader AI system can obtain when needed.
A language model does not have to contain every fact internally if it can recognize when information should be retrieved from a reliable external source.
This tool-using approach is becoming increasingly important as AI systems become more capable.
Why Models Can Appear to Reason
Some language-model responses involve multiple connected steps that resemble reasoning.
The model can compare alternatives, identify relationships, follow logical structures, and solve certain unfamiliar problems.
Part of this ability emerges because language contains enormous amounts of reasoning. Explanations, proofs, debates, instructions, code, and problem-solving examples all contain patterns connecting one idea to another.
As models become larger and training methods improve, they can become increasingly capable of applying these patterns to new situations.
Modern systems can also use specialized training and inference techniques designed to improve performance on complex problems.
Still, the fact that an answer contains a convincing chain of logic does not guarantee that every step is correct. Verification remains important when accuracy matters.
Why Scale Changed Everything
Small language models can learn grammar and basic patterns, but increasing model size, data quality, training computation, and architectural sophistication can produce dramatic improvements.
Larger systems have more capacity to represent complicated relationships.
They can maintain more nuanced contextual patterns, work across more domains, and generalize to tasks that were not individually programmed into them.
This produced one of the biggest surprises in modern AI research.
Capabilities began appearing that were not always obvious from the basic training objective.
A system trained heavily around predicting language could translate, summarize, explain, write code, classify information, answer questions, and perform many other tasks through the same general interface.
There Is No Tiny Writer Inside the Machine
The easiest mistake to make when interacting with a fluent language model is imagining a human-like author hidden behind the screen.
The output encourages that interpretation because language is something humans strongly associate with thought.
But underneath the conversation is a computational process.
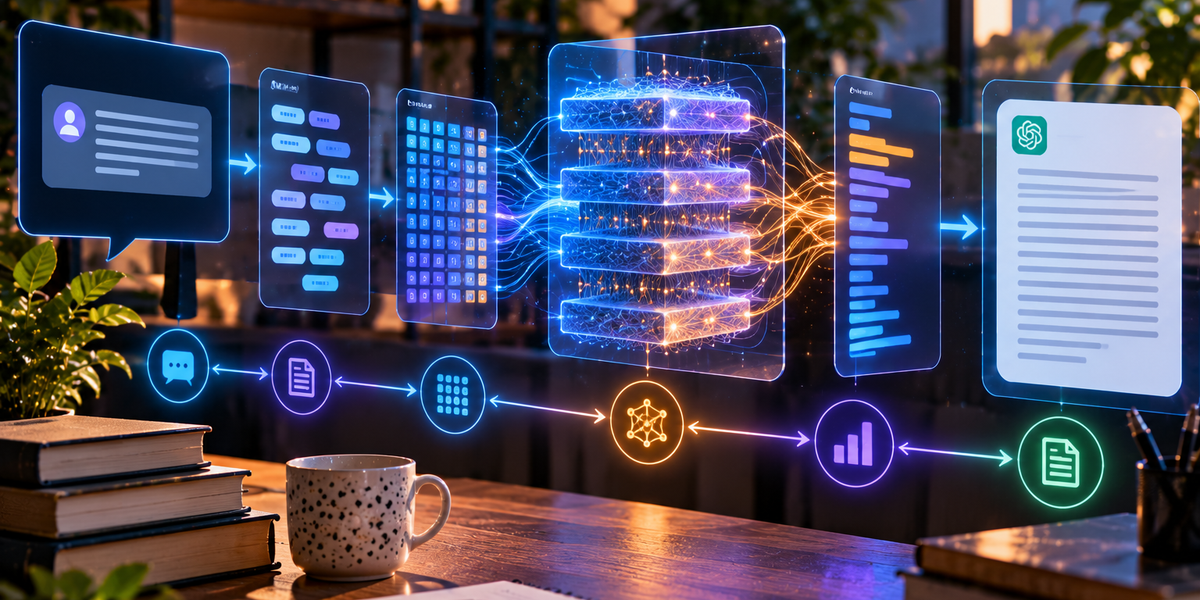
Your message becomes tokens. Those tokens become numerical representations. The neural network processes relationships throughout the context. The model calculates probabilities for possible continuations and selects another token. That token becomes part of the context, and the process repeats.
This happens rapidly enough that paragraphs appear almost immediately.
The mechanism is mathematical, but the patterns it learned came from human language, which is why the result feels so familiar.
The Simple Idea Behind an Extremely Complicated Machine
The central idea behind large language models can be summarized without advanced mathematics. Give a neural network enormous amounts of language-related training, ask it repeatedly to become better at predicting text, adjust its internal parameters whenever its predictions need improvement, and continue the process at extraordinary scale.
After training, provide the model with a prompt and ask it to predict what should come next. Add that prediction to the context and repeat the process until a complete response emerges.
That explanation sounds almost too simple for a system capable of writing essays, generating software, translating languages, analyzing documents, and carrying on conversations.
Yet that is part of what makes large language models so remarkable. The complexity is not hidden in one magical instruction telling the machine how to write. It is distributed across an enormous network that has learned countless relationships from data and training.
The model does not pull a finished answer from a secret library, and it does not have a tiny person inside composing paragraphs. It generates language one piece at a time, repeatedly asking, in mathematical terms, what should come next.
Do that well enough, across enough data, with a large enough model and sophisticated enough training, and something that began as prediction can produce text that feels remarkably like conversation.